
Google AI Business: Understanding Core Tools and Capabilities for Organizations refers to the set of cloud-hosted services, developer frameworks, and user-facing features that are intended to help organizations apply artificial intelligence across workflows. This concept covers models for generating text and images, machine learning platforms for training and managing models, data-processing and analytics services, and productivity integrations that embed AI features into document, communication, and operational tools. The focus is on how these elements can support tasks such as data analysis, content generation, automation of routine work, and model deployment, rather than on any single product name or marketing claim.
Within this topic, core capabilities are typically grouped by function: model development and lifecycle tools, data storage and analytics, API-based inference services, and workspace integrations for end users. Organizations may use combinations of these capabilities to address needs such as predictive modeling, natural language processing, document summarization, and process automation. Considerations often include scalability, latency, data residency, and the ability to monitor model behaviour; choices can vary depending on an organization’s technical profile and compliance requirements.
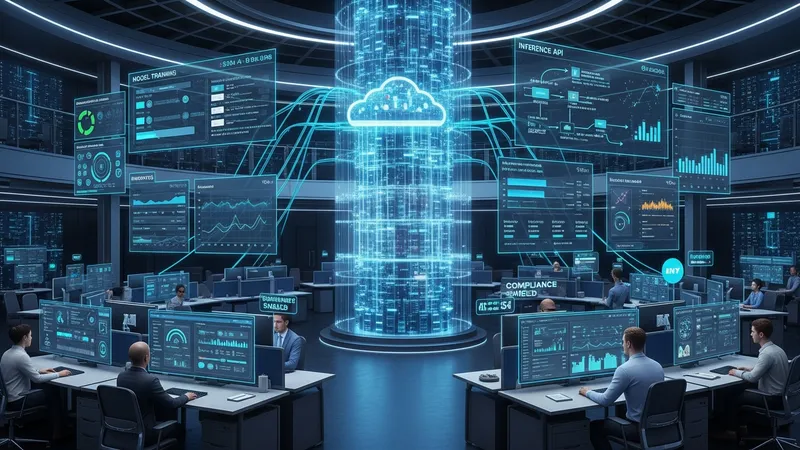
Organizations frequently combine these examples in end-to-end workflows: data is ingested into analytics storage, models are trained or fine-tuned using managed ML services, and inference is exposed via APIs or integrated into productivity platforms. Vendor documentation often describes usage-based pricing and recommended architectures; organizations typically estimate costs by modelling expected data volumes, training frequency, and inference request rates. Selection criteria used by technical teams commonly include supported model types, integration points with existing data systems, monitoring capabilities, and available compliance controls.
Generative capabilities and foundation models may be used for tasks such as draft content creation, summarization, and code assistance, but their outputs often require human review and established verification steps. When organizations adopt these features, they typically establish review workflows, metadata logging, and post-processing filters to manage accuracy and relevance. Model lifecycle practices — versioning, testing on representative datasets, and staged rollouts — can help reduce operational surprises. These practices are part of a broader governance approach that may include change control and accountable review processes.
Data infrastructure is a central element: robust ingestion, labeling, and feature engineering pipelines can affect model performance and maintainability. Analytics platforms with SQL-friendly interfaces often allow data teams to prototype models close to the data without moving large volumes externally. For larger model training tasks, distributed compute and managed services may be used; teams typically plan for data transfer costs, storage redundancy, and backup strategies. Data quality checks and lineage tracking are often recommended to support reproducibility and auditability of model outputs.
Security and compliance considerations usually encompass access controls, encryption in transit and at rest, and audit logging for model usage. Organizations often apply role-based access controls and separate environments for development and production to reduce risk. Monitoring for anomalous inference patterns and establishing incident response workflows for model-related incidents may be part of an operational security plan. Legal and privacy assessments often guide decisions around data retention, anonymization, and allowed use cases.
In summary, Google AI Business: Understanding Core Tools and Capabilities for Organizations frames a set of integrated services and practices for applying AI in operational contexts. It covers platforms for model development, data analytics, inference delivery, and productivity integration, along with governance and operational controls that organizations may implement. The next sections examine practical components and considerations in more detail.
Developer platforms and tool types relevant to Google AI Business: Understanding Core Tools and Capabilities for Organizations include managed ML platforms, analytics warehouses, data-processing pipelines, and API endpoints for inference. Managed ML platforms often provide interfaces for training, hyperparameter tuning, model registry, and deployment; they may support built-in algorithms and custom containerized models. Analytics warehouses typically offer SQL-based model creation and large-scale query engines that can be used for feature extraction. API endpoints and SDKs allow applications to call trained models for inference, and these are commonly wrapped with monitoring and quotas to control usage patterns.
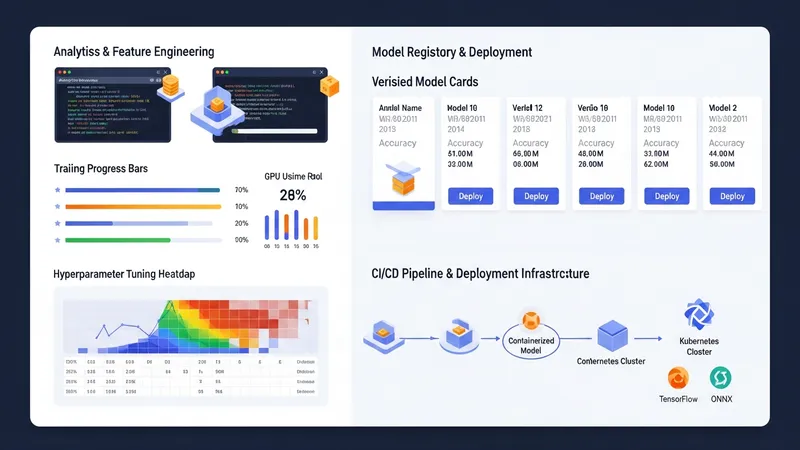
When evaluating types of tools, organizations often consider interoperability with existing CI/CD processes and data systems. Tools that integrate with common orchestration frameworks or support standard model formats (e.g., TensorFlow SavedModel, ONNX) may simplify deployment across environments. For teams that prefer low-code options, some platforms supply graphical model-building interfaces or AutoML-like capabilities; these can speed prototyping but may require additional scrutiny around transparency and control. Typical trade-offs include developer productivity versus the need for detailed model configuration and observability.
Data pipeline and preprocessing tools are frequently part of the same ecosystem and can range from streaming ingestion utilities to batch transformation services. Effective pipelines may include validation steps, label management for supervised learning, and versioned feature stores to ensure consistent feature calculation between training and serving. Organizations often plan for metrics that capture data drift and feature distribution changes, which may trigger model retraining or human review when thresholds are exceeded. These operational elements can influence tool selection and resource planning.
Insider considerations include planning for incremental adoption and skills development: teams may start with small, well-scoped pilots that use managed services to reduce operational overhead, then migrate to more custom setups as requirements mature. Documentation, community resources, and available professional support are practical factors that can affect developer ramp-up time. Organizations may also assess vendor-provided examples and reference architectures to estimate integration effort and ongoing maintenance responsibilities.
Data storage, access patterns, and analytics approaches are central to Google AI Business: Understanding Core Tools and Capabilities for Organizations because model quality and latency often depend on how data is managed. Data warehouses and lake architectures are commonly used to consolidate structured and semi-structured data, while streaming systems may handle near-real-time inputs. Feature engineering workflows may be implemented in-place with SQL or via ETL/ELT tools; the chosen approach typically depends on data velocity, team skills, and cost sensitivity. Organizations often monitor query and storage costs against expected throughput to size systems appropriately.
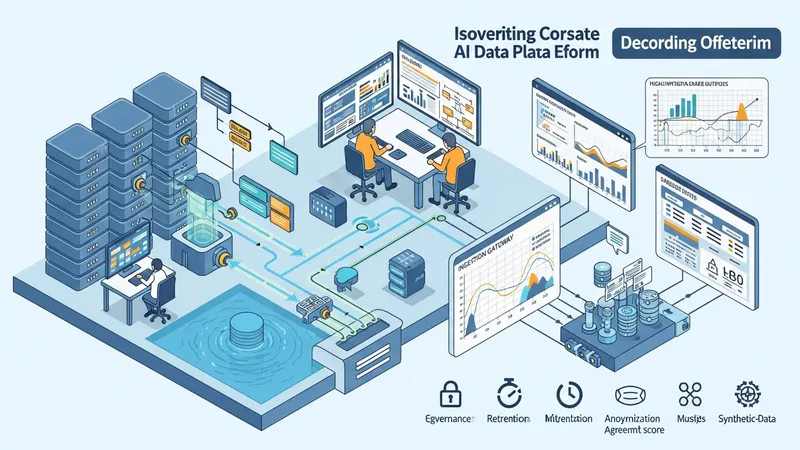
Effective analytics practices include rigorous data validation and lineage tracking so that results from models can be traced back to source datasets. Teams typically define schemas and enforce them at ingestion to reduce unexpected nulls or type mismatches. For supervised learning, labeled datasets often require a controlled labeling process and quality checks; some organizations maintain annotation tools and inter-annotator agreement metrics. Data governance policies that specify retention, access roles, and synthetic or anonymized alternatives are common when handling sensitive information.
Performance considerations for analytics-driven AI often involve balancing precomputation of features against on-the-fly calculation to meet latency targets. Precomputed feature stores can reduce serving costs and improve response consistency, while live calculation may be used for time-sensitive or highly dynamic inputs. Resource planning often includes estimates for storage, compute for batch processing, and network egress in distributed setups. Teams may prototype typical workloads to better estimate recurring costs and identify bottlenecks before committing to large-scale deployments.
Insider tips as considerations: maintain clear separation between experimental and production datasets, and adopt naming conventions and metadata standards to reduce operational confusion. Establishing a small set of standardized evaluation metrics—both offline (accuracy, precision, recall) and online (latency, error rates)—can help align stakeholders on when a model is ready for production. These steps may shorten troubleshooting cycles and support reproducible model updates over time.
Security and governance are integral to Google AI Business: Understanding Core Tools and Capabilities for Organizations because they influence trust, regulatory compliance, and operational stability. Access control frameworks typically include role-based permissions for data, model artifacts, and deployment endpoints. Encryption at rest and in transit is commonly enabled to protect sensitive data. Organizations often incorporate audit logging for model training and inference requests so that usage patterns can be inspected if incidents occur. These practices may form part of broader IT security policies and risk assessments.
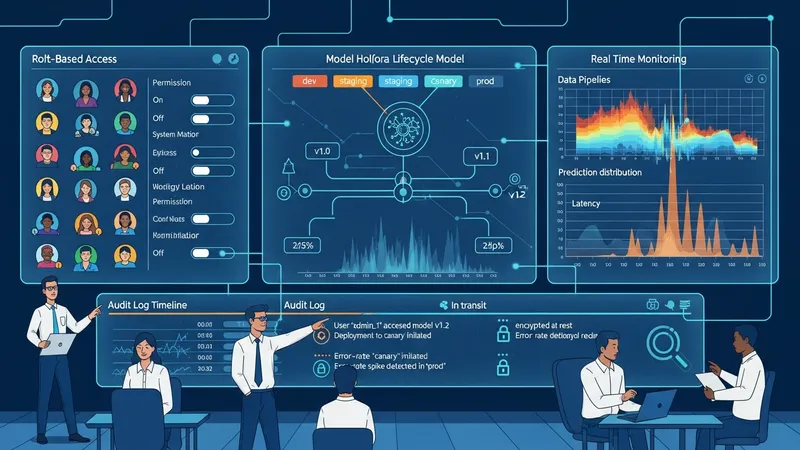
Governance around model lifecycle management often covers version control, testing procedures, and documented acceptance criteria for deployment. Teams may use staging environments and canary deployments to reduce the risk of regression when introducing new models. Monitoring systems that track prediction distributions, latency, and error rates can signal when models require retraining or rollback. Compliance-related activities commonly include data minimization, purpose limitation, and privacy impact assessments when models process personal data.
Operational resilience considerations include backup strategies for model artifacts and configuration, as well as established procedures for rollback and incident response. Teams typically define service-level objectives for model endpoints, including expected uptime and maximum acceptable latency. Load testing with representative traffic patterns may reveal scaling needs and help size autoscaling policies. Planning for maintenance windows and controlled deployments is often part of an organizational process to coordinate changes with dependent systems.
Practical insider considerations emphasize documentation and clear ownership: assigning stewards for datasets, models, and monitoring dashboards can reduce ambiguity during incidents. Regularly scheduled reviews of models and access permissions may uncover drift and stale privileges. Establishing minimal reproducible experiments and retaining training data snapshots may support audits or retrospective analyses without requiring full-scale reprocessing of historical data.
Integration and deployment are key concerns within Google AI Business: Understanding Core Tools and Capabilities for Organizations because they determine how AI features reach users and systems. Common patterns include deploying models as RESTful or gRPC endpoints, embedding model calls within microservices, or integrating AI-assisted features directly into productivity workflows via APIs and connectors. Continuous integration and continuous delivery (CI/CD) pipelines for models may automate testing, validation, and staged rollouts. These patterns often aim to reduce manual steps and improve reproducibility across environments.
Lifecycle practices often include automated testing for model performance and regression checks that compare new versions to baseline metrics. Blue-green or canary deployment strategies are typically used to limit exposure while monitoring behaviour under production load. Observability components commonly include metrics for request volume, latency, error rates, and model-specific indicators such as prediction confidence distributions. Traceability between training runs and deployed models is often maintained using metadata stores or model registries.
Interoperability considerations may affect the choice of model formats and deployment targets; support for portable formats and containerization can simplify migration between environments. For low-latency inference, organizations sometimes use edge deployment or specialized inference accelerators. Cost and latency trade-offs are typically evaluated when deciding whether to centralize serving in cloud regions or move computation closer to users. Integration testing that includes downstream systems helps validate end-to-end behaviour before broad rollout.
Insider tips presented as considerations include starting with clear success criteria for pilot deployments and iterating on integration patterns that minimize coupling between model logic and business workflows. Maintain clear documentation for API contracts and expected data formats to reduce integration friction. Finally, schedule periodic reviews of deployed models to assess ongoing relevance, technical debt, and alignment with evolving business requirements.